Qwen Image 3.0 vs GPT Image 2: Which Wins in 2026?
Qwen Image 3.0 vs GPT Image 2 tested across text, layouts, speed, UI and image quality, with a reproducible protocol and evidence from X.
 Qwen Image 3.0

The tutorial images in this guide are newly generated testing references. They are not claimed as outputs from either model.
The short answer to Qwen Image 3.0 vs GPT Image 2 is less dramatic than launch-day posts suggest. GPT Image 2 still has the stronger all-round record in the public tests reviewed here. It produced cleaner English copy, steadier detail and faster results in the most systematic five-scene comparison. Qwen Image 3.0 made the decision genuinely interesting in three narrower areas: dense Chinese layouts, structured UI and cost-sensitive access.
That makes Qwen Image 3.0 vs GPT Image 2 a workflow decision. A restaurant menu with French accents and a Chinese event poster are both “text in an image,” but they expose different failure modes. One asks for spelling and typographic restraint. The other asks the model to preserve Chinese glyphs while managing a crowded hierarchy. The right model changes with the job.
Qwen Image 3.0 vs GPT Image 2: verdict and evidence limits
This guide reviews public X posts published around July 21–23, 2026. The strongest single source is thehypedotnews’ five-scene test, which covered a supermarket flyer, a refined menu, an analytics dashboard, a newspaper column and a fashion cover. GPT Image 2 won four; fashion was close. The post also reported roughly one-minute GPT generations against roughly two to four minutes for four Qwen runs, with the fashion result closer.
Those numbers are useful, but they are not a service-level promise. The post does not establish identical back-end load, seeds or interface settings. The wider Qwen Image 3.0 vs GPT Image 2 evidence has the same limitation: it is a set of practical observations, not a controlled lab benchmark.
| Question | What the public evidence supports | What it does not prove |
|---|---|---|
| Overall winner | GPT Image 2 led most cited general-quality comparisons | Every test will favor GPT |
| Speed | GPT was faster in thehype’s five runs | A universal latency guarantee |
| Chinese text | Qwen preserved labels and dense hierarchy in several examples | Perfect Chinese copy at every size |
| English long copy | GPT produced cleaner menu and newspaper text | Error-free production artwork |
| Cost and access | Testers called Qwen free, cheap or locally accessible | Permanent free access or a fixed price |
Qwen Image 3.0 vs GPT Image 2 Features comparison
The following Qwen Image 3.0 vs GPT Image 2 table describes observed behavior, not marketing specifications.
| Feature | Qwen Image 3.0 | GPT Image 2 | Practical call |
|---|---|---|---|
| Overall detail | Improved sharply over Qwen 2.0, but local softness and noise still appeared | Richer scenes and steadier fine detail in multiple side-by-sides | GPT |
| English text | Short labels can work; long copy still showed misspellings and gibberish | Cleaner menu spelling and more coherent newspaper copy in thehype test | GPT |
| Chinese layout | Often kept more Chinese information and clearer hierarchy | Strong first impression, but Chinese labels failed in Simon’s Suzhou example | Qwen |
| Dense composition | Can fit a lot into one poster, sometimes too much | More selective and visually balanced in several examples | Depends on the brief |
| UI mockups | One of the few diffusion systems praised for structured UI | Usually more polished in direct comparisons | GPT for polish, Qwen for cheap iteration |
| Faces and physical consistency | Community comments still flag faces, noise and local logic | More reliable in cited character-reference tests | GPT |
| Observed speed | About 2–4 minutes in four of the five cited runs | About one minute in the same post | GPT |
| Access | Often described as free or inexpensive during launch testing | Paid access assumptions vary by product surface | Verify current terms |
Mark K’s post, with roughly 311 likes and 17,000 views in the supplied snapshot, captures the English-language mood: Qwen 3.0 is a real step forward, but it has not displaced GPT Image 2 on quality and reliability. HerissonTemich made a similar call. This is stronger social proof than a string of anonymous praise because the accounts, posts and reactions remain inspectable.
Qwen Image 3.0 vs GPT Image 2 in five identical-brief cases
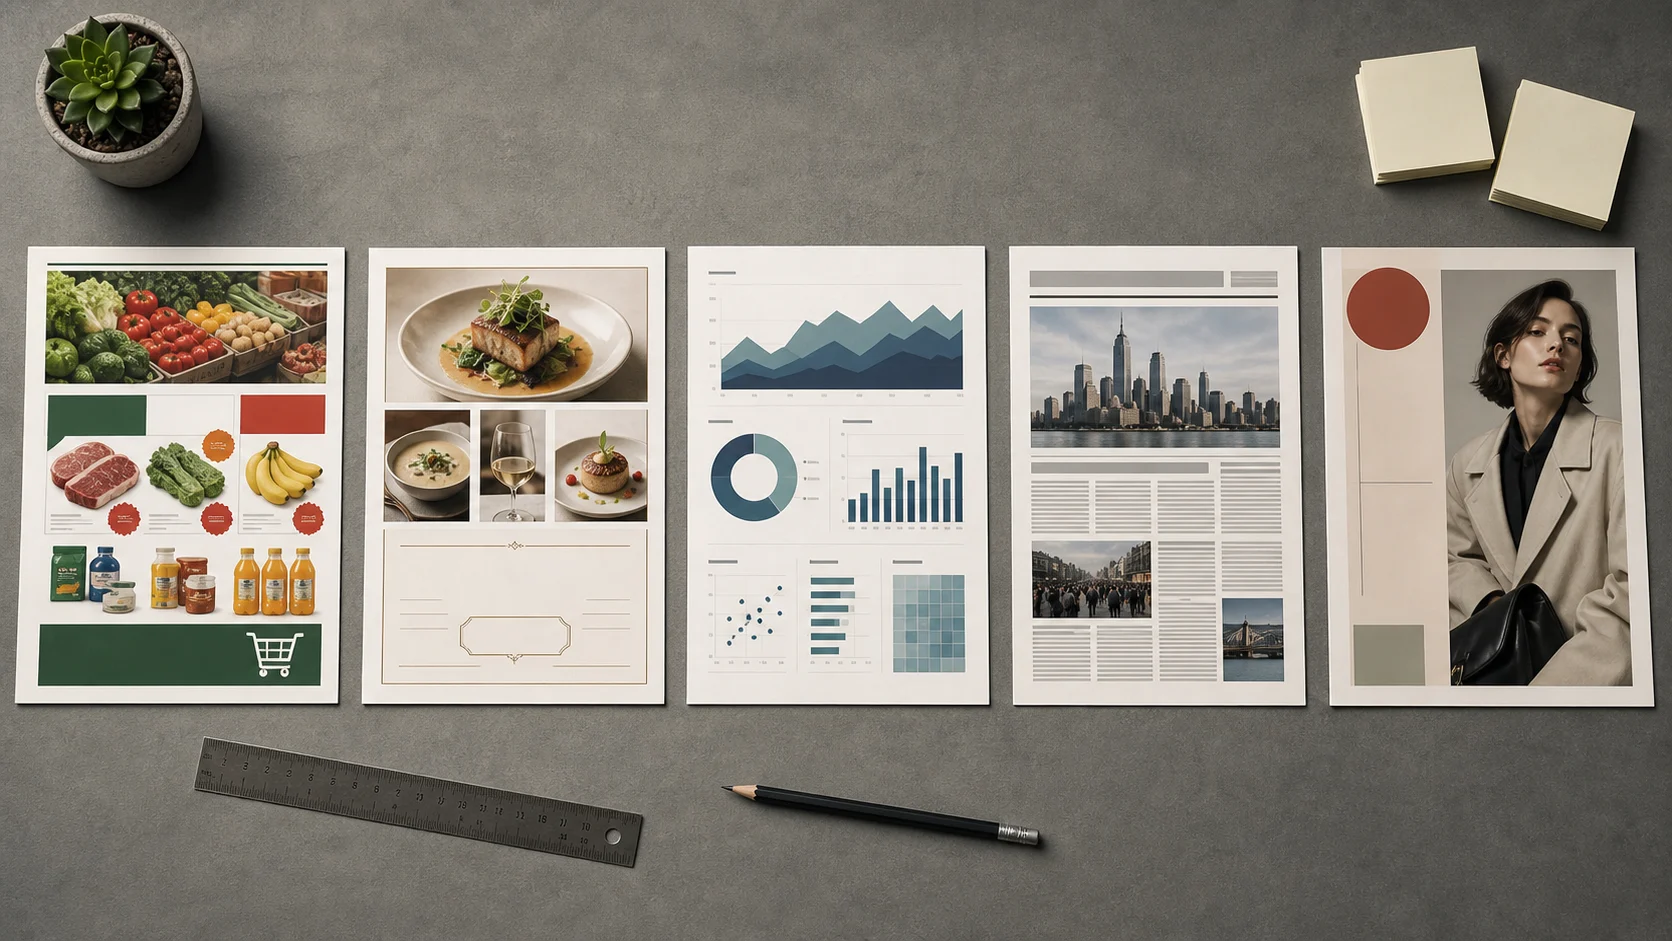
Reference board for the five test categories. It illustrates the protocol and does not reproduce either model’s outputs.
The supermarket flyer test favored GPT for coherence and finish. Qwen carried plenty of information, but the layout felt heavier and less resolved. That pattern agrees with lionman888888’s Chinese poster comparison: Qwen retained the most text and hierarchy and had a strong Y2K/guochao flavor, yet it could become crowded and top-heavy. GPT delivered the strongest first impression.
The menu was more decisive. Qwen produced “thryme” and “rosted fennel.” GPT kept “crème fraîche” intact. These are small errors with a large production cost. A designer cannot ship a menu that merely looks correctly spelled.
The dashboard showed why Qwen Image 3.0 vs GPT Image 2 is not a simple wipeout. pwnies called Qwen one of the few diffusion models able to render usable UI structure. GPT still looked richer in the cited comparison, but Qwen produced something designers could use for layout exploration.
The newspaper exposed long-copy coherence. GPT generated plausible article text. Qwen’s body copy looked like gibberish and introduced an incorrect Argentina-style striped jersey. Fashion was the near tie, where preference depended more on art direction.
Qwen Image 3.0 vs GPT Image 2 Tutorial: a fair test you can repeat
Do not compare one hand-picked Qwen image with one hand-picked GPT image. Use this compact protocol:
- Freeze one private brief, one aspect ratio and one delivery size.
- Put every required string in quotation marks. List copy separately from visual direction.
- Generate four images per model. Keep the failed ones.
- Record elapsed time. Note whether the interface was free, queued or rate-limited.
- Score text accuracy, brief coverage, composition, physical consistency and repeatability from 0 to 5.
- Count repair work. A prettier image that takes 25 minutes to fix may cost more than a plain image that is correct.
Here is a reusable scoring sheet:
| Run | Text accuracy | Required objects | Layout | Visual quality | Physical logic | Repair minutes |
|---|---|---|---|---|---|---|
| A1–A4 | /5 | /5 | /5 | /5 | /5 | |
| B1–B4 | /5 | /5 | /5 | /5 | /5 |
This Qwen Image 3.0 vs GPT Image 2 Tutorial makes preference visible. A creative director may weight visual quality twice. A localization team may reject a single wrong glyph.
Qwen Image 3.0 vs GPT Image 2 Use Case: dense Chinese posters
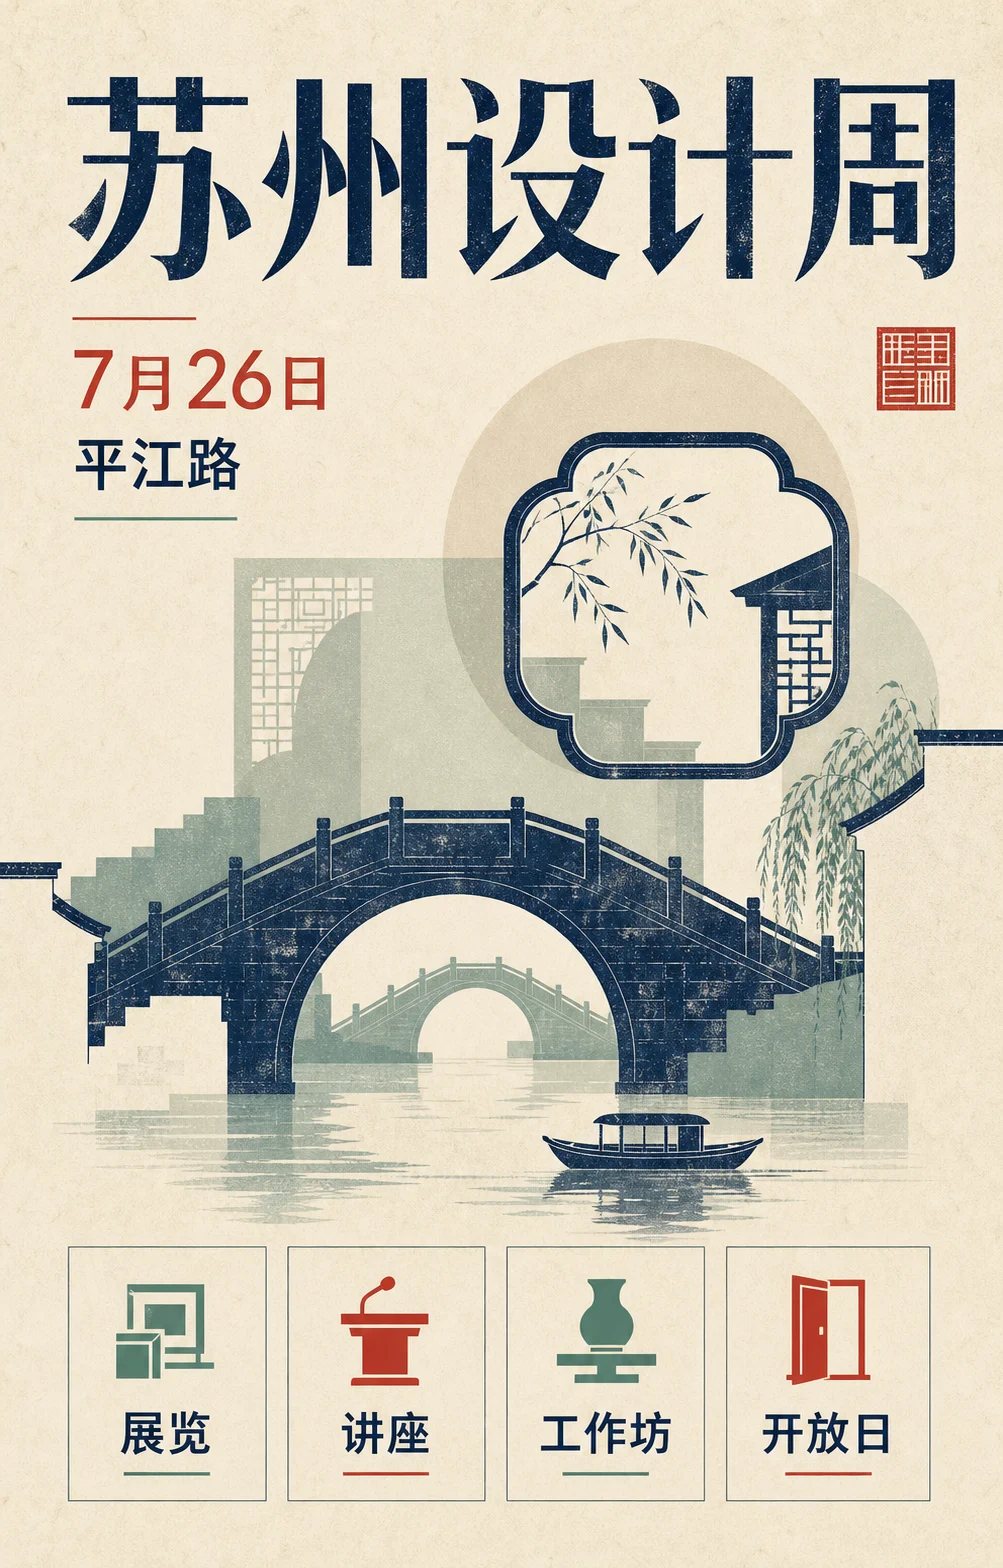
Newly generated test reference. The large type and multiple text fields make errors easy to count.
For a private test brief, lock four variables before generation: a vertical delivery ratio, a fixed Chinese copy list, two or three regional visual motifs, and a defined information grid. Keep that internal brief identical for both models. Score missing characters, malformed glyphs, duplicated copy and whether the lower information modules retain equal visual weight.
The private test separates copy, visual motifs and layout. Simon’s Suzhou test explains why it is useful: GPT had the better overall visual, while Qwen got the Chinese annotations right. For a campaign team, run Qwen Image 3.0 vs GPT Image 2 twice: first score glyph accuracy, then let designers score the image without knowing the model.
Qwen Image 3.0 vs GPT Image 2 Use Case: menus and long Latin text
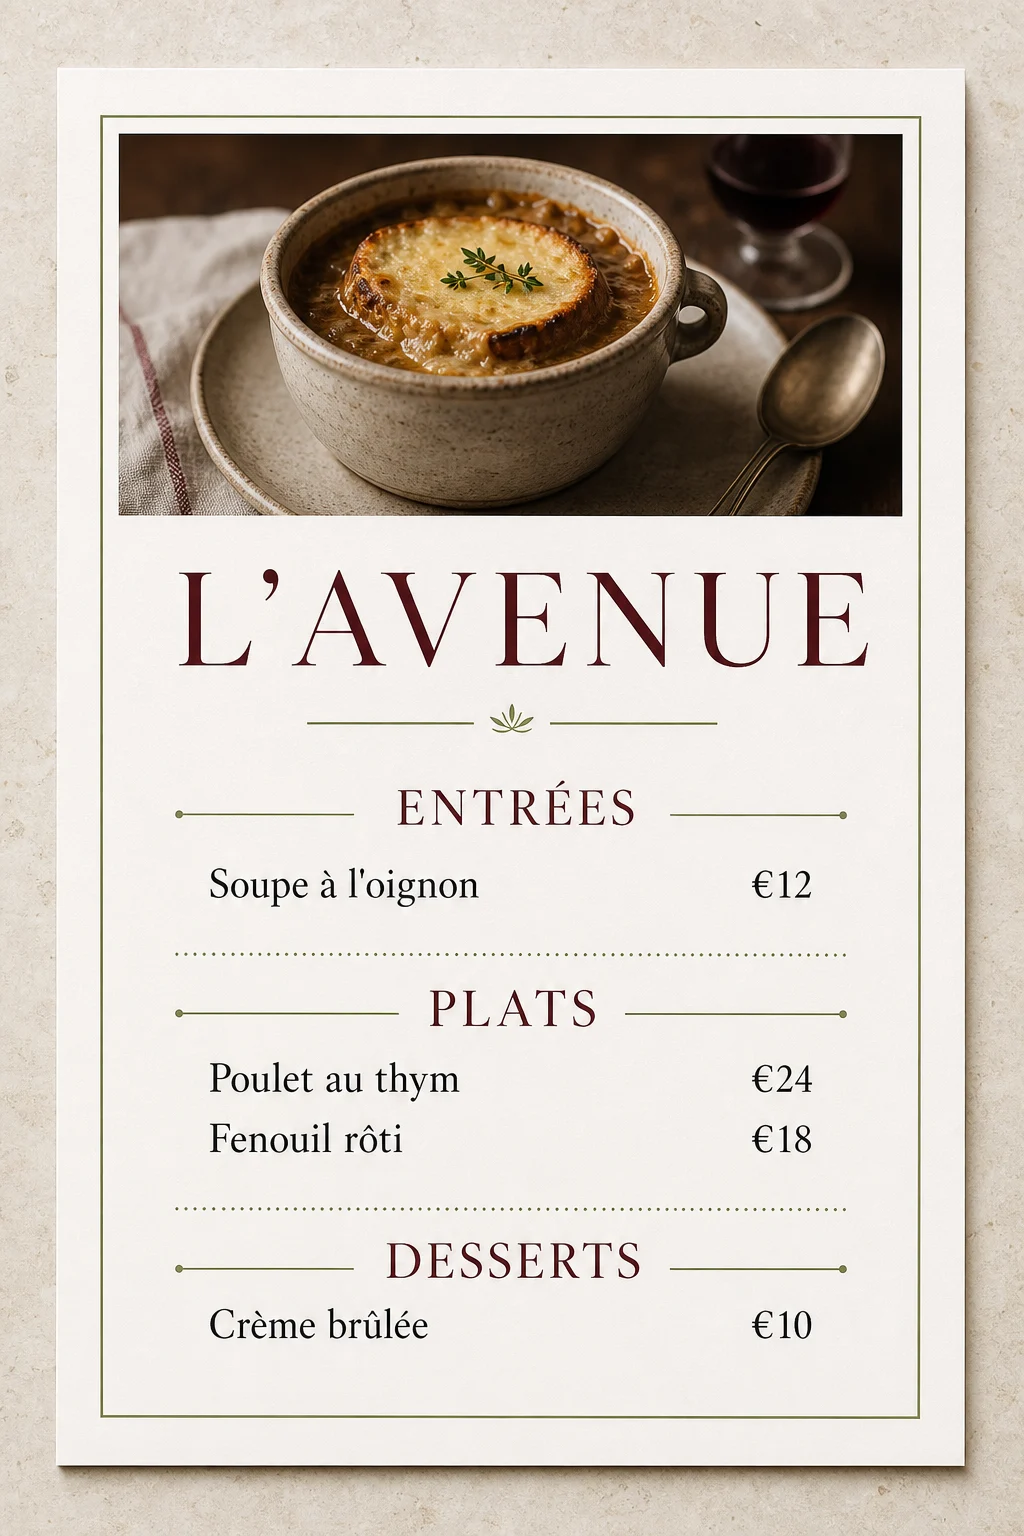
Build the private menu test around accented words, apostrophes, prices, section headings and repeated alignment rules. Use the same confidential copy for both models, then check accents, duplicate words, price alignment and baseline rhythm. Thehype’s result suggests GPT Image 2 is the safer first choice. Still proofread every output. Image models are not typesetting systems.
Qwen Image 3.0 vs GPT Image 2 Use Case: UI and dashboards
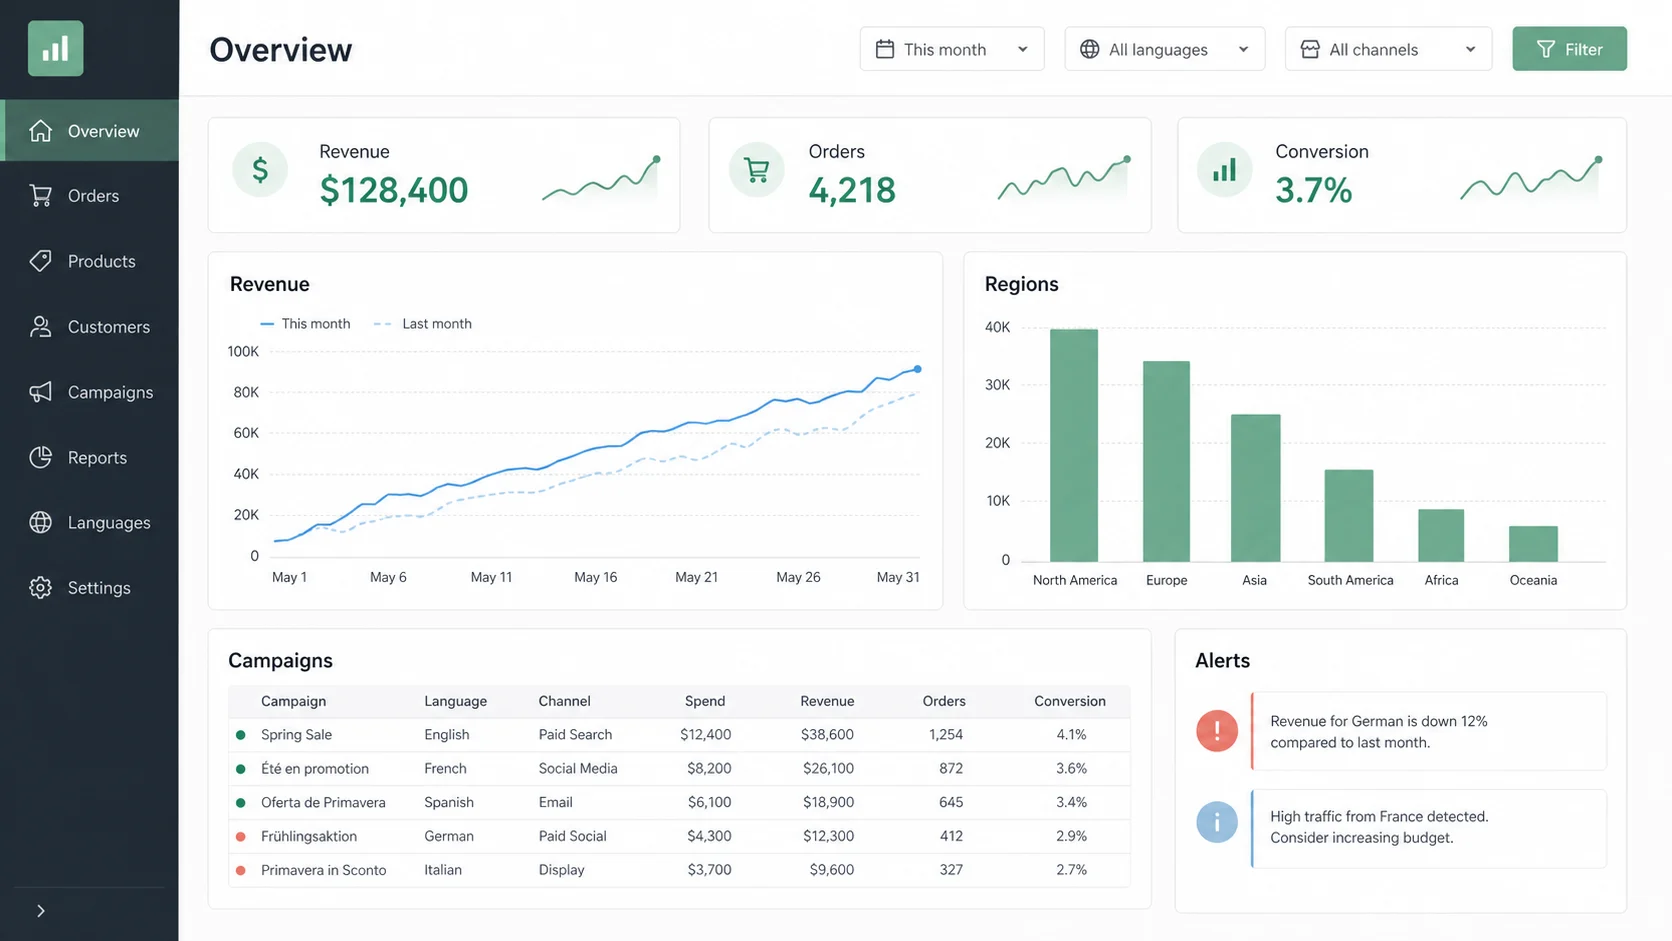
For UI, visual plausibility is only half the test. Keep an internal specification with a fixed navigation pattern, KPI count, chart types, table columns and label set. Inspect whether chart axes agree with the data, table columns align and repeated components share spacing. Qwen’s UI strength makes it useful for early exploration. GPT’s richer finish can reduce art-direction work. Neither output should go straight into production code.
Qwen Image 3.0 vs GPT Image 2 user testimonials
The useful testimonials disagree in specific ways:
- Xudong07452910 preferred GPT’s richer content, softer color and stable detail, while noting Qwen’s free access made it competitive.
- aiden_cckk saw more color noise in Qwen but slightly preferred its aesthetic. Taste did not track reliability.
- chuyouqi ranked character-reference results GPT Image 2 first, Qwen 3.0 second and Qwen 2.0 last among the listed group.
- cedric_chee said artifacts had improved but typography remained below GPT, and also criticized the move from open to closed.
- AbleGPT shared the more positive case: Chinese long text, multilingual material, UI and editing can approach Image 2 while staying cheaper and locally accessible.
That disagreement is the honest social proof. Qwen Image 3.0 vs GPT Image 2 has a stable overall leader and several use cases where the runner-up may be the better tool.
Why Qwen Image 3.0 can be the best GPT Image 2 alternative free option
Qwen is the better candidate when your job combines Chinese copy, dense layout and a tight experimentation budget. The wording “GPT Image 2 alternative free” needs a date attached: testers described Qwen as free or cheap during the launch window. Check current terms before building a production pipeline around that assumption.
Choose GPT Image 2 when English spelling, realistic detail, faces, rapid iteration or dependable first-pass quality has the highest cost. Choose Qwen when Chinese integrity and fitting more structured information matter more, or when you need many low-cost layout drafts. For important work, use both: Qwen for structure, GPT for visual alternatives, and a real design tool for final typography.
Qwen Image 3.0 vs GPT Image 2 FAQ
Is Qwen Image 3.0 better than GPT Image 2?
Not overall in the evidence reviewed here. GPT leads quality, English long copy, speed and reliability. Qwen is stronger in several Chinese and dense-layout cases.
Is Qwen Image 3.0 permanently free?
The cited community snapshot supports free or low-cost access at that moment. It does not prove permanent pricing.
Can either model deliver final production text?
Treat all generated text as a draft. Export the image and typeset final copy in Figma, Photoshop or another layout tool when correctness matters.
What is the best first test brief?
Use the actual artifact you need. Keep exact copy, required objects, aspect ratio and layout constraints in a private brief, then generate a batch. A vague request cannot answer Qwen Image 3.0 vs GPT Image 2 for your workflow.
The community verdict is sensible: GPT Image 2 remains the safer all-round choice. Qwen Image 3.0 is close enough in dense Chinese design and UI to earn a real test. Try Qwen Image 3.0 on the homepage, keep every result, and score it against the same private brief before you decide.